THE MAKING OF / After-hours party
Bring the room into the performance.
A solo rapper, a silver cup and a room full of reactions. Explore the real reference photo, generated party clip and complete prompt for this warm, handheld scene.
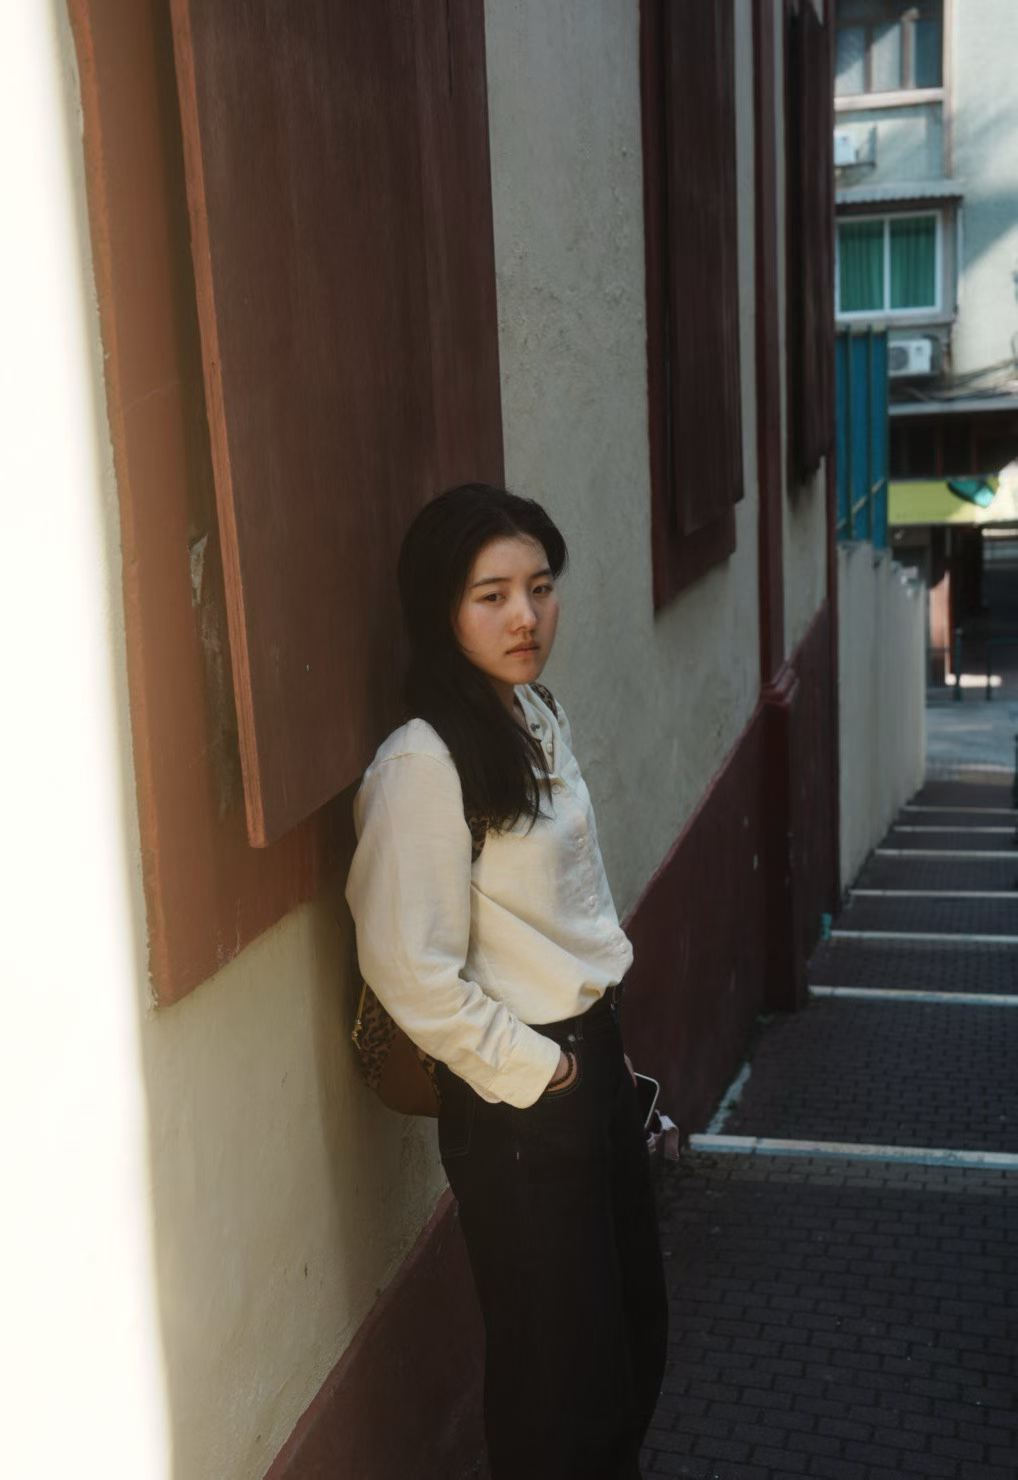
The starting point.
A single reference image guides the lead performer. Friends, the chandelier and the room are described in the prompt rather than supplied as additional photos.
Every direction, word for word.
This prompt follows the lead from a direct-to-camera verse to a toast with friends, then back to the lens. It specifies the same silver cup throughout and gentle handheld framing.
生成一段 15 秒的室内派对说唱。以参考图 1 中的人物为唯一领唱,保持面部特征、发型和体型一致。主角穿深色微反光夹克、深色内搭,戴反扣棒球帽和简洁项链,一只手始终握着同一只银色金属杯。场景是昏暗暖色的聚会房间,头顶有水晶吊灯,深色木质门框、墙镜和数位朋友构成背景,灯光有柔和金色反射。开头主角在近景中直视镜头说唱,随节奏点头和晃肩,杯子放在胸腹之间,另一只手轻摆。中段主角边唱边转向身旁朋友,举杯致意,再用空着的手指向朋友,身后的人举手、笑着回应,保持自然拥挤的派对气氛。后段主角重新面向镜头,小步靠近,伸出空着的手强调一句歌词,随后收手并继续摇摆说唱。横屏手持中近景,镜头轻微后退与左右跟随,偶尔让朋友进入画面边缘,保留吊灯和室内空间感,不插入其他场景。脸部始终可辨认,杯子不换手、不增多,衣服和朋友位置前后连贯。生成原创派对说唱、低沉贝斯和紧凑鼓点,不使用原曲、原歌手声音、视频片段、字幕或水印。Make the next take yours.
Keep the useful details and change what makes the scene your own.
- 01
Set the lead’s look
Use your own reference photo and update the dark jacket, cap and necklace details if they do not match your character.
- 02
Keep one consistent prop
The silver cup stays in the same hand. If you choose another prop, replace every mention and leave the other hand free for gestures.
- 03
Direct the reactions
Describe friends nodding, smiling and returning the toast at the frame edges. Keep the lead’s face visible as the camera moves.
Create your rap video.
What carries over?
Will using this prompt recreate the same video?
Each generation is a new result. The prompt and settings are reused, while your photos guide the performers. Faces, movement, timing and audio can vary. The photos shown above are not automatically attached to your generation.
Are the friends in the video taken from uploaded photos?
Only the lead performer had a reference photo in this example. The surrounding friends and their reactions are generated from the scene description. Their faces and positions may vary in your result.